AI Token Economics: How to Forecast LLM Costs
AI token economics explained: how LLM inference is priced per token, how to forecast cost per user as usage grows, and which levers cut the bill.
Blockphrase Team
- Published
- Reading time
- 8 min read
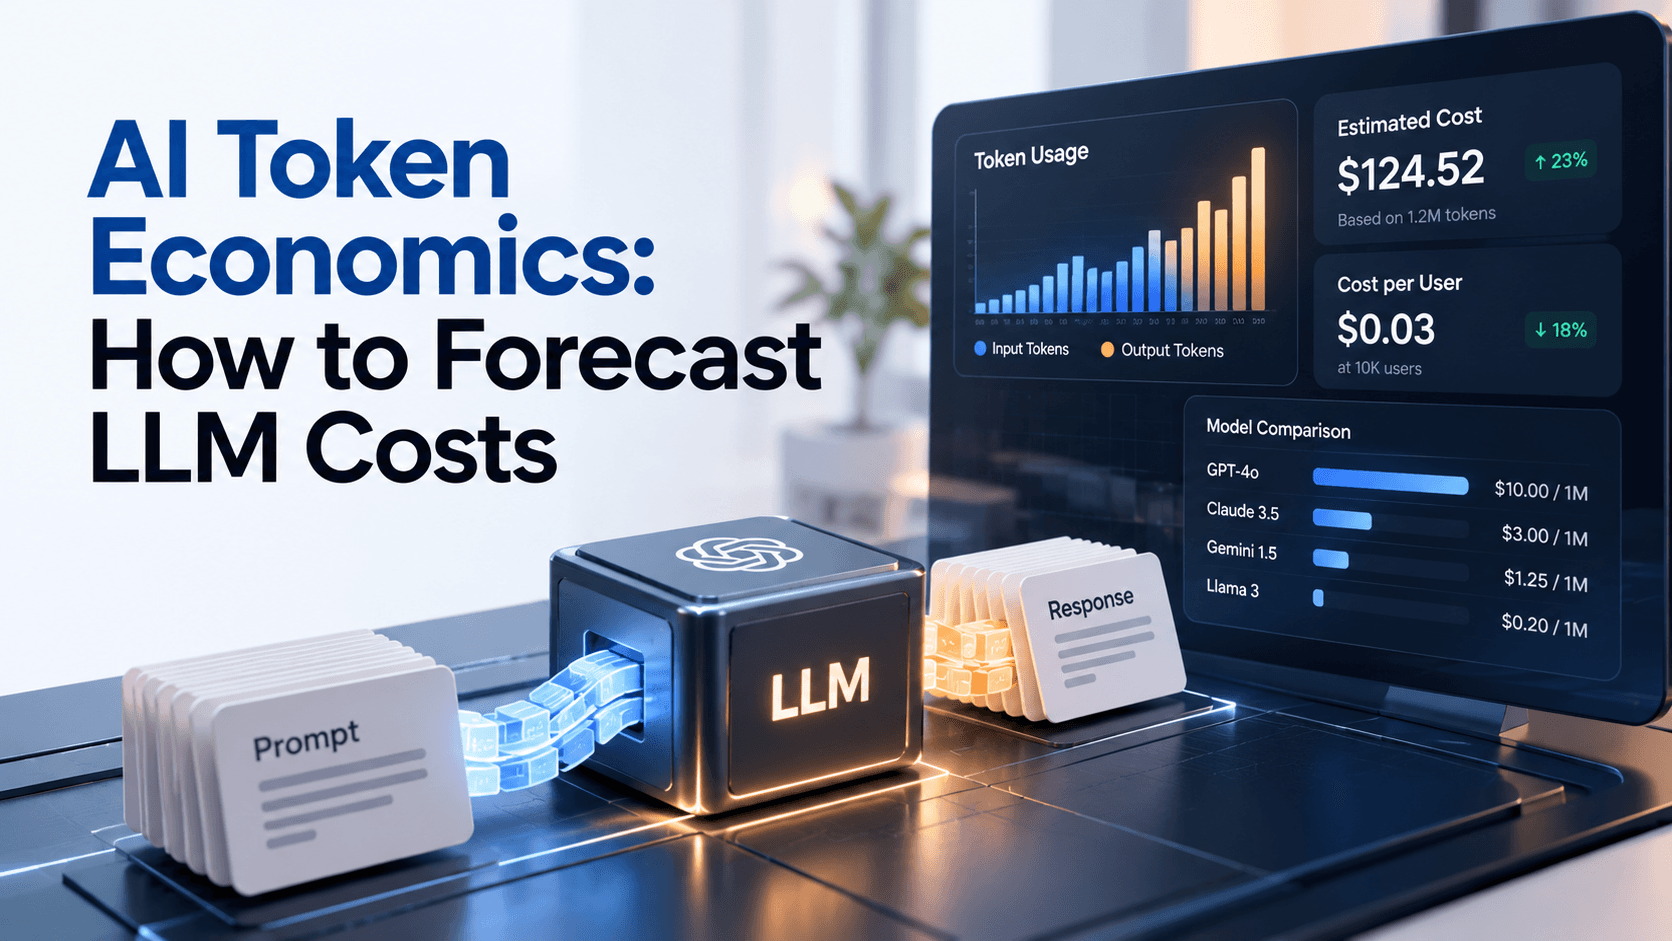
An AI product's inference bill is the number of tokens it sends and receives, multiplied by each provider's per-token rates, which are usually set separately for input and output. To forecast it, model tokens per request, requests per user and users over time, then apply the discounts you actually qualify for: cached input, batch processing and cheaper models for simpler work.
The tokens in this post are the units of text an AI model reads and writes. They are not crypto tokens, and nothing here concerns a token sale, a blockchain or a market price.
What Is an LLM Token and How Is It Priced?
A token is a fragment of text. Google's Gemini documentation puts it at about 4 characters, with 100 tokens equal to about 60-80 English words. Each model family has its own tokenizer, so the same prompt can count differently on two providers.
The major providers bill per token, per million tokens, with separate rates for input and output. On their pricing pages as read on October 21, 2026, OpenAI, Anthropic and Google all list input and output prices per million tokens, and on their current flagship models output costs five or six times the input rate, with higher ratios on some other models.
Three other line items sit beside the base rates:
- Cached input. Repeated prompt prefixes can be billed at a fraction of the input rate. Anthropic charges cache hits at 0.1x the base input price on most models, and less on some newer ones. OpenAI lists cached-input and cache-write prices for its main models.
- Batch. Work that can wait is discounted. OpenAI's Batch API offers a 50% cost discount with a 24-hour turnaround; Anthropic charges 50% of standard prices; Google lists its Batch API at a 50% cost reduction.
- Location and context length. OpenAI adds a 10% uplift for regional processing endpoints on models released on or after March 5, 2026, and Anthropic applies a 1.1x multiplier for US-only inference on Claude 4.6 and later models. Some Gemini models carry higher rates for prompts over 200k tokens, while Anthropic bills most current Claude models at the same per-token rate across the full 1M-token context window.
What Drives the Cost of One Request?
On the input side: the system prompt, tool definitions, any retrieved documents, the conversation so far and the user's message. On the output side: the visible answer, plus any reasoning the model does before answering.
That last part is easy to miss. OpenAI states that reasoning tokens are not visible through the API but still occupy space in the context window and are billed as output tokens. Google's pricing table labels its output price "including thinking tokens". A short visible answer can still carry a long, expensive output count.
The formula for one request:
Cost per request = (uncached input × input rate) + (cached input × cached rate) + (cache writes × write rate) + (output, including reasoning, × output rate).
Measure each term from real traffic. Provider APIs report token usage per call (Google's, for example, returns counts for input, output, thinking and cached content), and that log, not the prompt you wrote, is the basis of the model.
How Do You Build Cost per User and per Feature?
Start from features, not from the monthly invoice. A product with chat, document summaries and a nightly digest has three cost profiles, each with its own prompt size, output length, model and latency need.
For each feature, record four things: average input tokens (split into cached and uncached), average output tokens including reasoning, calls per use (an agent may make several model calls for one user action), and which model serves it.
Then multiply up:
- Cost per use = cost per call × calls per use
- Cost per user per month = sum over features of (uses per user per month × cost per use)
- Monthly bill = active users × cost per user per month
Track the distribution, not just the average. A small group of heavy users can set the bill, and a flat subscription price has to cover them.
What Does the Math Look Like? A Hypothetical Example
The figures below are invented, round numbers chosen to show the method. They are illustrative, not a quote from any provider's price list (some list prices happen to be similar), and they do not describe any real product.
For example, a team runs a support assistant on a model priced at an illustrative $2 per million input tokens and $10 per million output tokens. Each request sends 6,000 input tokens (a 3,000-token system prompt and tool definitions, 2,000 tokens of retrieved help articles, 1,000 tokens of conversation and question) and generates 1,000 output tokens, half of them reasoning.
- Input: 6,000 × $2 / 1,000,000 = $0.012
- Output: 1,000 × $10 / 1,000,000 = $0.010
- Cost per request: $0.022
A typical user sends 20 requests a day on 25 days a month, so 500 requests: $11.00 per user per month. If the plan sells for $20 a month, inference alone takes 55% of revenue before hosting, support or payment fees.
Now apply three levers to the same hypothetical:
- Cache the 3,000-token static prefix at an illustrative 10% of the input rate: input falls to $0.0066 (ignoring the occasional cache write), and the request costs $0.0166.
- Cap and tighten output so the average falls from 1,000 to 700 tokens: output falls to $0.007, and the request costs $0.0136.
- Route half the traffic, the simple questions, to a model priced at one-fifth: those requests cost about $0.0027, and the blended average is about $0.0082.
Cost per user per month falls from $11.00 to about $4.08. Each step assumes answer quality holds, which only an evaluation on real conversations can confirm.
Why Do Inference Costs Compound as Usage Grows?
The bill can grow faster than the user count for three reasons.
Conversation history is resent. Anthropic's documentation describes how each user message and assistant response accumulates within the context window, and the input phase contains all previous history plus the new message. In the hypothetical above, if each turn adds 700 tokens (a 200-token question and a 500-token visible answer), the tenth turn carries 6,300 tokens of earlier conversation, and a ten-turn session resends 31,500 history tokens in total. Input per turn grows in a straight line, so total input across a session grows with the square of the number of turns.
Usage per user rises. Engaged users send more requests and longer documents, so cost per user is not a constant.
Features add calls. Agents that plan, call tools and retry multiply calls per action, and reasoning models add output tokens the user never sees.
A forecast that holds cost per user flat while users grow will undershoot if any of these terms rises. Model it as users × requests per user × tokens per request, with each term on its own growth curve.
Which Levers Cut LLM Costs?
| Lever | What it changes | Trade-off |
|---|---|---|
| Model choice and routing | Rate paid per token | Smaller models can miss hard cases; needs testing |
| Shorter prompts and context | Input tokens per call | Cutting context the model needs hurts answers |
| History trimming or summaries | Input growth per turn | Older detail is lost |
| Prompt caching | Price of repeated prefixes | Exact prefix match only; writes can cost more; caches expire |
| Batch processing | 50% off input and output | Results can take up to 24 hours |
| Output limits | Output and reasoning tokens | Answers can be cut off mid-response |
Some details from the providers matter here. Anthropic's cache needs 100% identical prompt segments and has a 5-minute default lifetime; its 5-minute cache writes cost 1.25x the base input price, so caching pays off after one cache read. OpenAI's minimum cacheable prompt is 1,024 tokens for GPT-5.6 and later. Anthropic's caching multipliers stack with the Batch API discount.
Output caps need care with reasoning models. OpenAI warns that hitting max_output_tokens can end a response before any visible output is produced, so you pay for input and reasoning and get no answer.
On routing, Anthropic's own cost advice is to choose Haiku for simple tasks, Sonnet for most production workloads, and Opus for the most complex reasoning. The principle carries across providers: pay top rates only for the requests that need them.
Where Do Teams Get the Forecast Wrong?
- Pricing the prompt, not the conversation. A cost sheet built from one call misses history growth.
- Ignoring reasoning tokens. They are billed as output and do not appear in the answer.
- Counting calls per user action as one. Agents and retries multiply calls.
- Assuming a cache hit rate. Any change to the prefix, such as a timestamp near the top of the prompt, breaks the exact match.
- Freezing prices. Rates change on announced dates. Google's page lists some Gemini rates as valid through November 30, 2026, with higher rates starting December 1, 2026. A forecast should record the rate and the date it was read.
Blockphrase's AI model token economics work models token usage and cost by provider, forecasts spend against usage growth and builds unit economics per user or feature, the same discipline behind its tokenomics services. To check your own numbers, book a scoping call.
Frequently Asked Questions
How many words are in one LLM token?
Fewer than one on average. Google's Gemini documentation says a token is about 4 characters, and 100 tokens equal about 60-80 English words. The ratio depends on the tokenizer, the language and the content, so code, numbers and non-English text can use more tokens. Count with the provider's own tools before forecasting.
Are reasoning tokens billed as output tokens?
Yes, on the providers that state it. OpenAI says reasoning tokens are not visible through the API but are billed as output tokens, and Google prices output "including thinking tokens". A short visible answer can therefore carry a large output count. Log reasoning separately so the forecast shows where output spend comes from.
When does prompt caching actually save money?
When the same long prefix is reused often enough within the cache's lifetime. On Anthropic's API a 5-minute cache write costs 1.25x the input price and a hit 0.1x on most models, so it pays after one hit. Any change inside the prefix breaks the match, so keep stable content first and variable content last.
How often should an LLM cost forecast be updated?
Whenever a rate, a model or a prompt changes, and on a fixed monthly cycle otherwise. Providers publish scheduled price changes: Google lists some Gemini rates valid through November 30, 2026, with higher rates from December 1, 2026. Record the date each rate was read, and compare forecast with billed usage every month.
Sources
Provider pages were read on October 21, 2026.